Publications

Research on video generation, agentic AI, multimodal reasoning, and AI for healthcare.

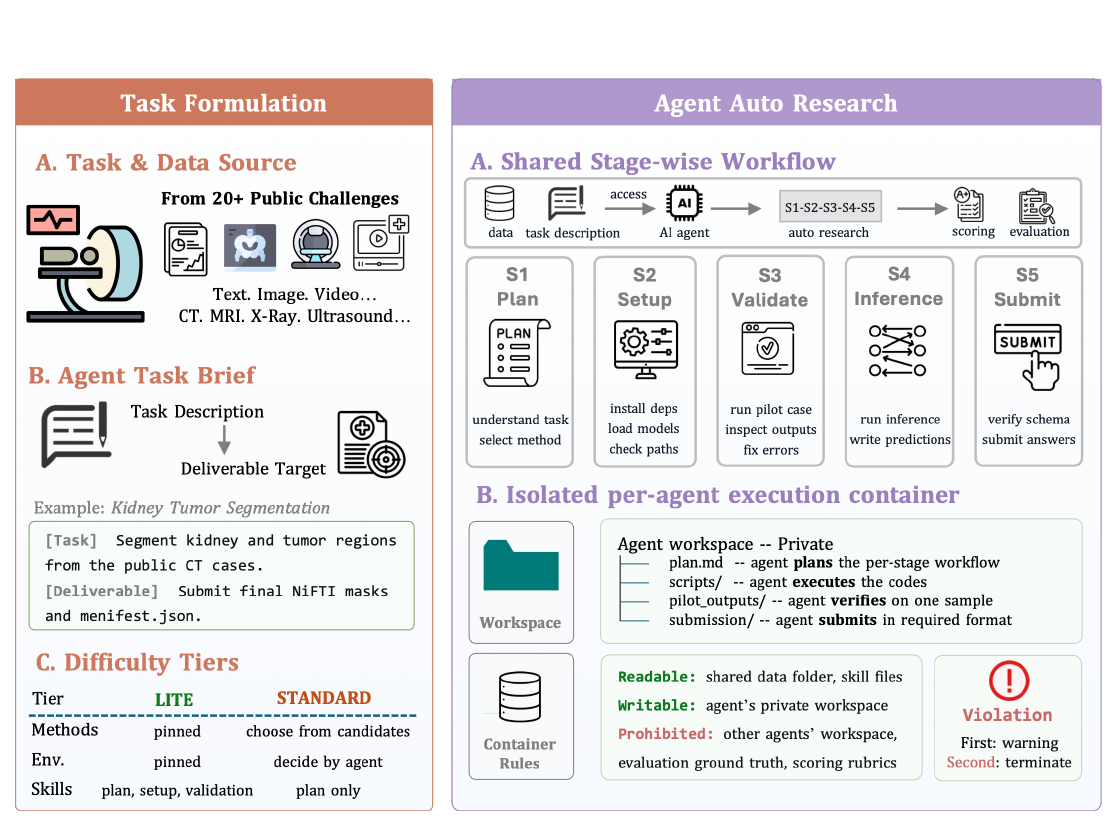
Representative figure for AutoMedBench: Towards Medical AutoResearch with Agentic AI Models

AutoMedBench: Towards Medical AutoResearch with Agentic AI Models

Junqi Liu, Selena Song, Yuhan Wang, Jiawei Mao, Hardy Chen, Xiaoke Huang, Tianhao Qi, Pengfei Guo, Yucheng Tang, Yufan He, Can Zhao, Andriy Myronenko, Dong Yang, Daguang Xu, Yuyin Zhou

arXiv:2606.01961 2026

A workflow-aware benchmark for evaluating autonomous agents across long-horizon medical-AI research tasks.
PaperCodeWebpage
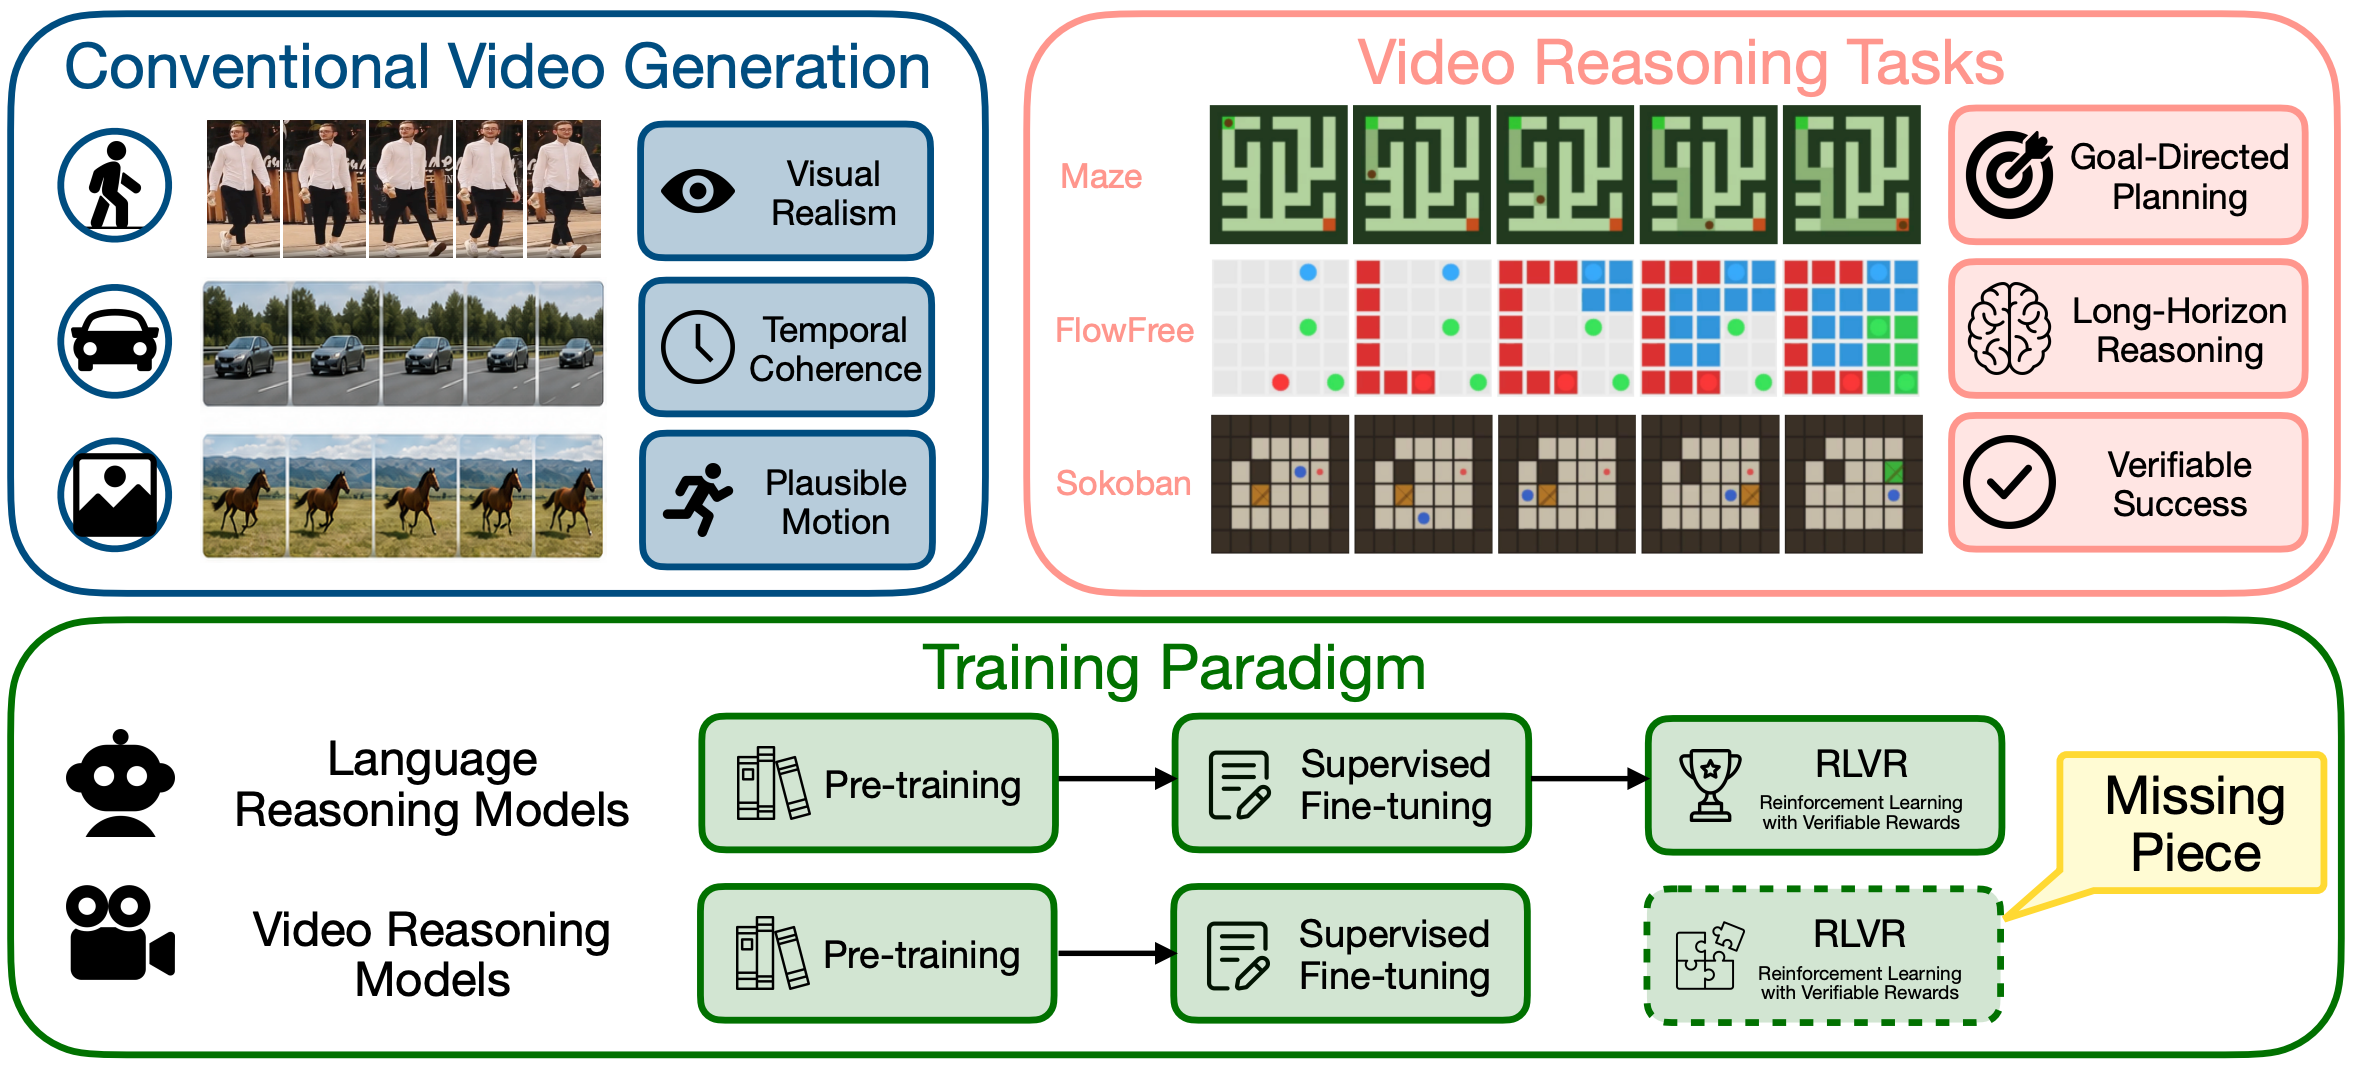
Representative figure for Video Models Can Reason with Verifiable Rewards

Video Models Can Reason with Verifiable Rewards

Tinghui Zhu, Sheng Zhang, James Y. Huang, Selena Song, Xiaofei Wen, Yuankai Li, Hoifung Poon, Muhao Chen

arXiv:2605.15458 2026

A reinforcement-learning recipe that trains video diffusion models to produce rule-consistent, verifiable visual trajectories.

PaperCodeWebpage
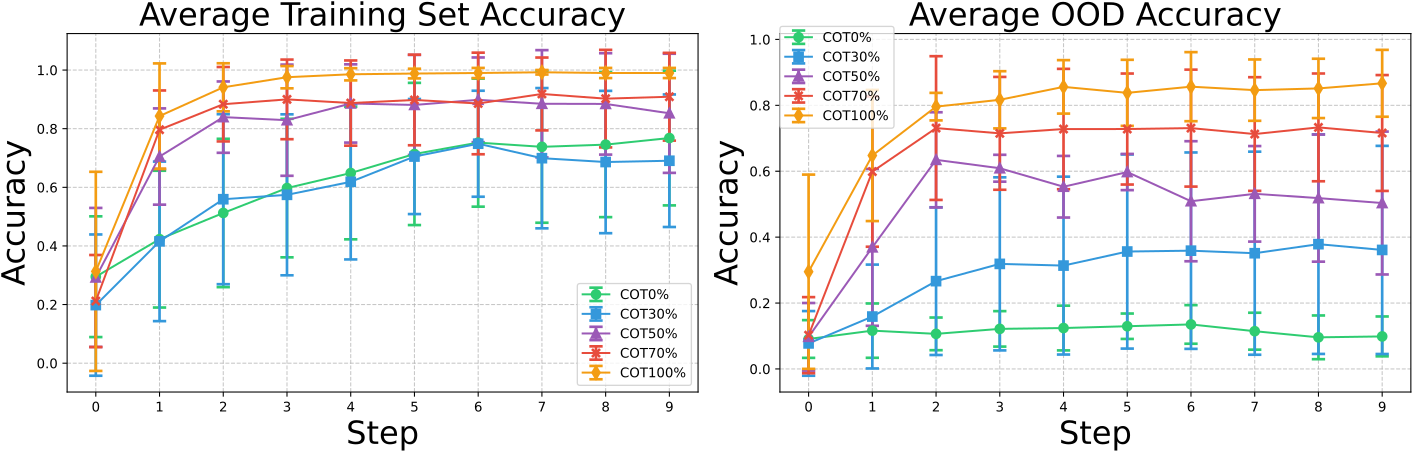
Representative figure for Beyond In-Distribution Success: Scaling Curves of CoT Granularity for Language Model Generalization

Beyond In-Distribution Success: Scaling Curves of CoT Granularity for Language Model Generalization

Ru Wang†, Wei Huang†, Selena Song, Haoyu Zhang, Qian Niu, Yusuke Iwasawa, Yutaka Matsuo, Jiaxian Guo

Conference on Parsimony and Learning (CPAL) 2026

Shows how Chain-of-Thought granularity shapes sample efficiency and out-of-distribution generalization.

Paper
Representative figure for Learning Plug-and-Play Memory for Guiding Video Diffusion Models

Learning Plug-and-Play Memory for Guiding Video Diffusion Models

Selena Song†, Ziming Xu†, Zijun Zhang, Kun Zhou, Jiaxian Guo, Lianhui Qin, Biwei Huang

arXiv:2511.19229 2025

A compact plug-and-play memory that injects physical-world priors into frozen video diffusion models.

PaperCodeWebpage
Representative figure for MMA: Benchmarking Multi-Modal Large Language Model in Ambiguity Contexts

MMA: Benchmarking Multi-Modal Large Language Model in Ambiguity Contexts

Selena Song†, Ru Wang†, Liang Ding, Mingming Gong, Yusuke Iwasawa, Yutaka Matsuo, Jiaxian Guo

ICLR 2025 DATA-FM Workshop; CPAL 2026 2025

The first benchmark designed to test whether MLLMs use visual context to resolve ambiguous language.

PaperWebpage