
Alibaba Tongyi Lab
Research Intern
–
Shanghai, China

Ph.D. Student in Computer Science
University of California, Santa Cruz
I am a Ph.D. student at the University of California, Santa Cruz, advised by Prof. Yuyin Zhou and Prof. Cihang Xie. My research interest lies in Video Generation, Agentic AI, and AI for Healthcare, with the goal of building reliable models that can reason, plan, and act in complex real-world environments.
Previously, I was a visiting graduate student at the University of California, San Diego, advised by Prof. Biwei Huang. I received my Master's degree in Engineering from The University of Tokyo in 2025 and my Bachelor's degree in Physics from Fudan University in 2023.
🎉Our paper Video Models Can Reason with Verifiable Rewards is accepted to NeurIPS 2026!
🎉I started my Ph.D. in Computer Science at UC Santa Cruz, advised by Prof. Yuyin Zhou.
Start an internship at Alibaba Tongyi Lab.
💡New paper on medical AutoResearch agents. Check AutoMedBench: Towards Medical AutoResearch with Agentic AI Models!
🎉Our paper Beyond In-Distribution Success: Scaling Curves of CoT Granularity for Language Model Generalization is accepted to CPAL 2026!
🎉Our paper MMA: Benchmarking Multi-Modal Large Language Model in Ambiguity Contexts is accepted to CPAL 2026!
💡New paper on plug-and-play memory for video diffusion models. Check Learning Plug-and-Play Memory for Guiding Video Diffusion Models!
Research Intern
–
Shanghai, China

Selena Song†, Ziming Xu†, Zijun Zhang, Kun Zhou, Jiaxian Guo, Lianhui Qin, Biwei Huang
arXiv:2511.19229
A compact plug-and-play memory that injects physical-world priors into frozen video diffusion models.

Selena Song†, Ru Wang†, Liang Ding, Mingming Gong, Yusuke Iwasawa, Yutaka Matsuo, Jiaxian Guo
ICLR 2025 DATA-FM Workshop; CPAL 2026
The first benchmark designed to test whether MLLMs use visual context to resolve ambiguous language.
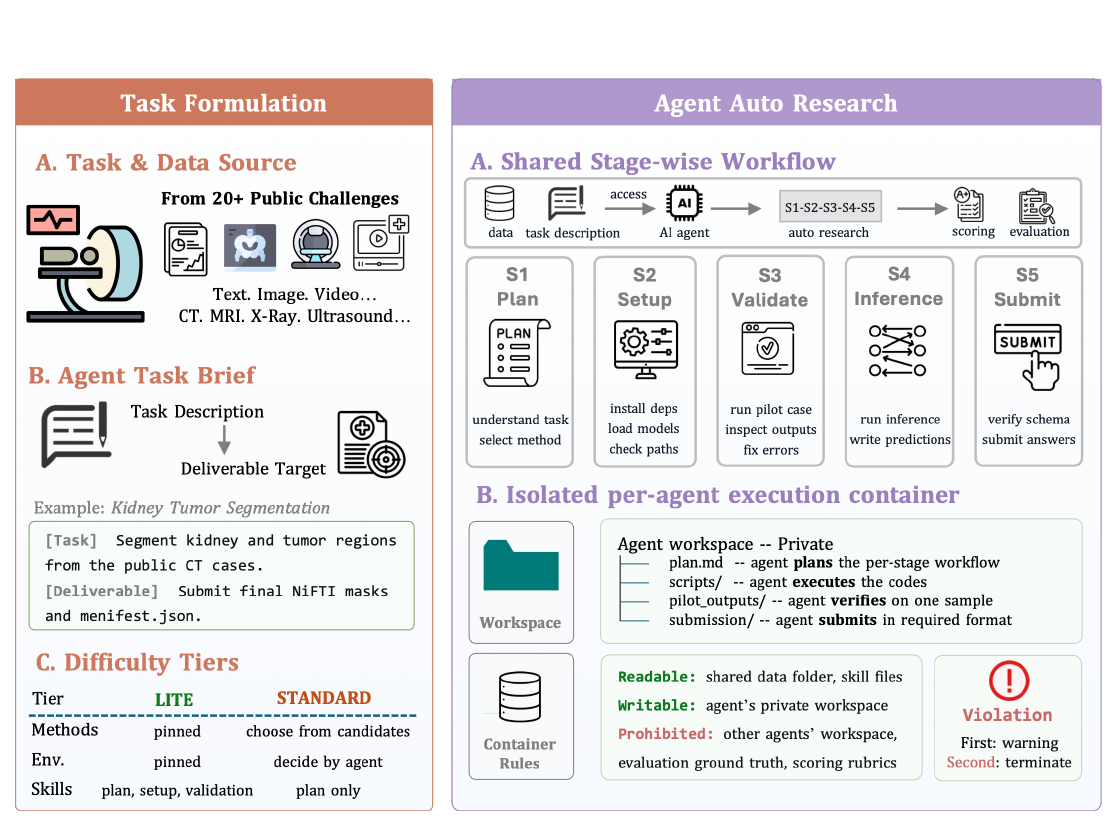
Junqi Liu, Selena Song, Yuhan Wang, Jiawei Mao, Hardy Chen, Xiaoke Huang, Tianhao Qi, Pengfei Guo, Yucheng Tang, Yufan He, Can Zhao, Andriy Myronenko, Dong Yang, Daguang Xu, Yuyin Zhou
arXiv:2606.01961
A workflow-aware benchmark for evaluating autonomous agents across long-horizon medical-AI research tasks.